
All articles — Page 13
How to deploy and integrate MCP servers with CodeRabbit
MCP servers integrate AI agents into software applications to carry out system-related tasks based on users’ requests. Platforms like Slack, Sentry, Notion, and GitHub Copilot have adopted MCP-style services to expose their features to AI-driven appl....
GPT-5.1 for code-related tasks: higher signal at lower volume
TL;DRAfter prompt tuning and integrating it into our stack, GPT-5.1 now delivers the best precision and signal-to-noise ratio (SNR) we’ve seen in reviews, with fewer comments. It tied for the best-in-class error pattern (EP) recall on our hard benchm....
Why emojis suck for reinforcement learning
The simplicity trap Sure, a thumbs up is quick, but is it really teaching your AI reviewer anything useful? Emoji-based feedback feels good, is fast, and universal. On the surface, it even seems to make sense. But code review isn’t a light switch. It....
The rise of ‘Slow AI’: Why devs should stop speedrunning stupid
For as long as we’ve been building with machines, we’ve followed one core rule: faster is better. Lower latency, higher throughput, less waiting; that was gospel. Nobody wanted to wait 600ms for a button to respond or watch a spinner that lasts longe....
The end of one-sized-fits-all prompts: Why LLM models are no longer interchangeable
For developers and product builders, one assumption has guided the last few years of LLM application development. To improve your product, just swap in the latest frontier large language model. Flip a single switch and your tool’s capabilities level ....
Claude Sonnet 4.5: better performance but a paradox
Sonnet 4.5 is Anthropic’s newest Claude model and in our code review benchmark, it feels like a paradox: more capable, more cautious, and at times more frustrating. It catches bugs Sonnet 4 missed, edges closer to Opus 4.1 in coverage, and even surfa...
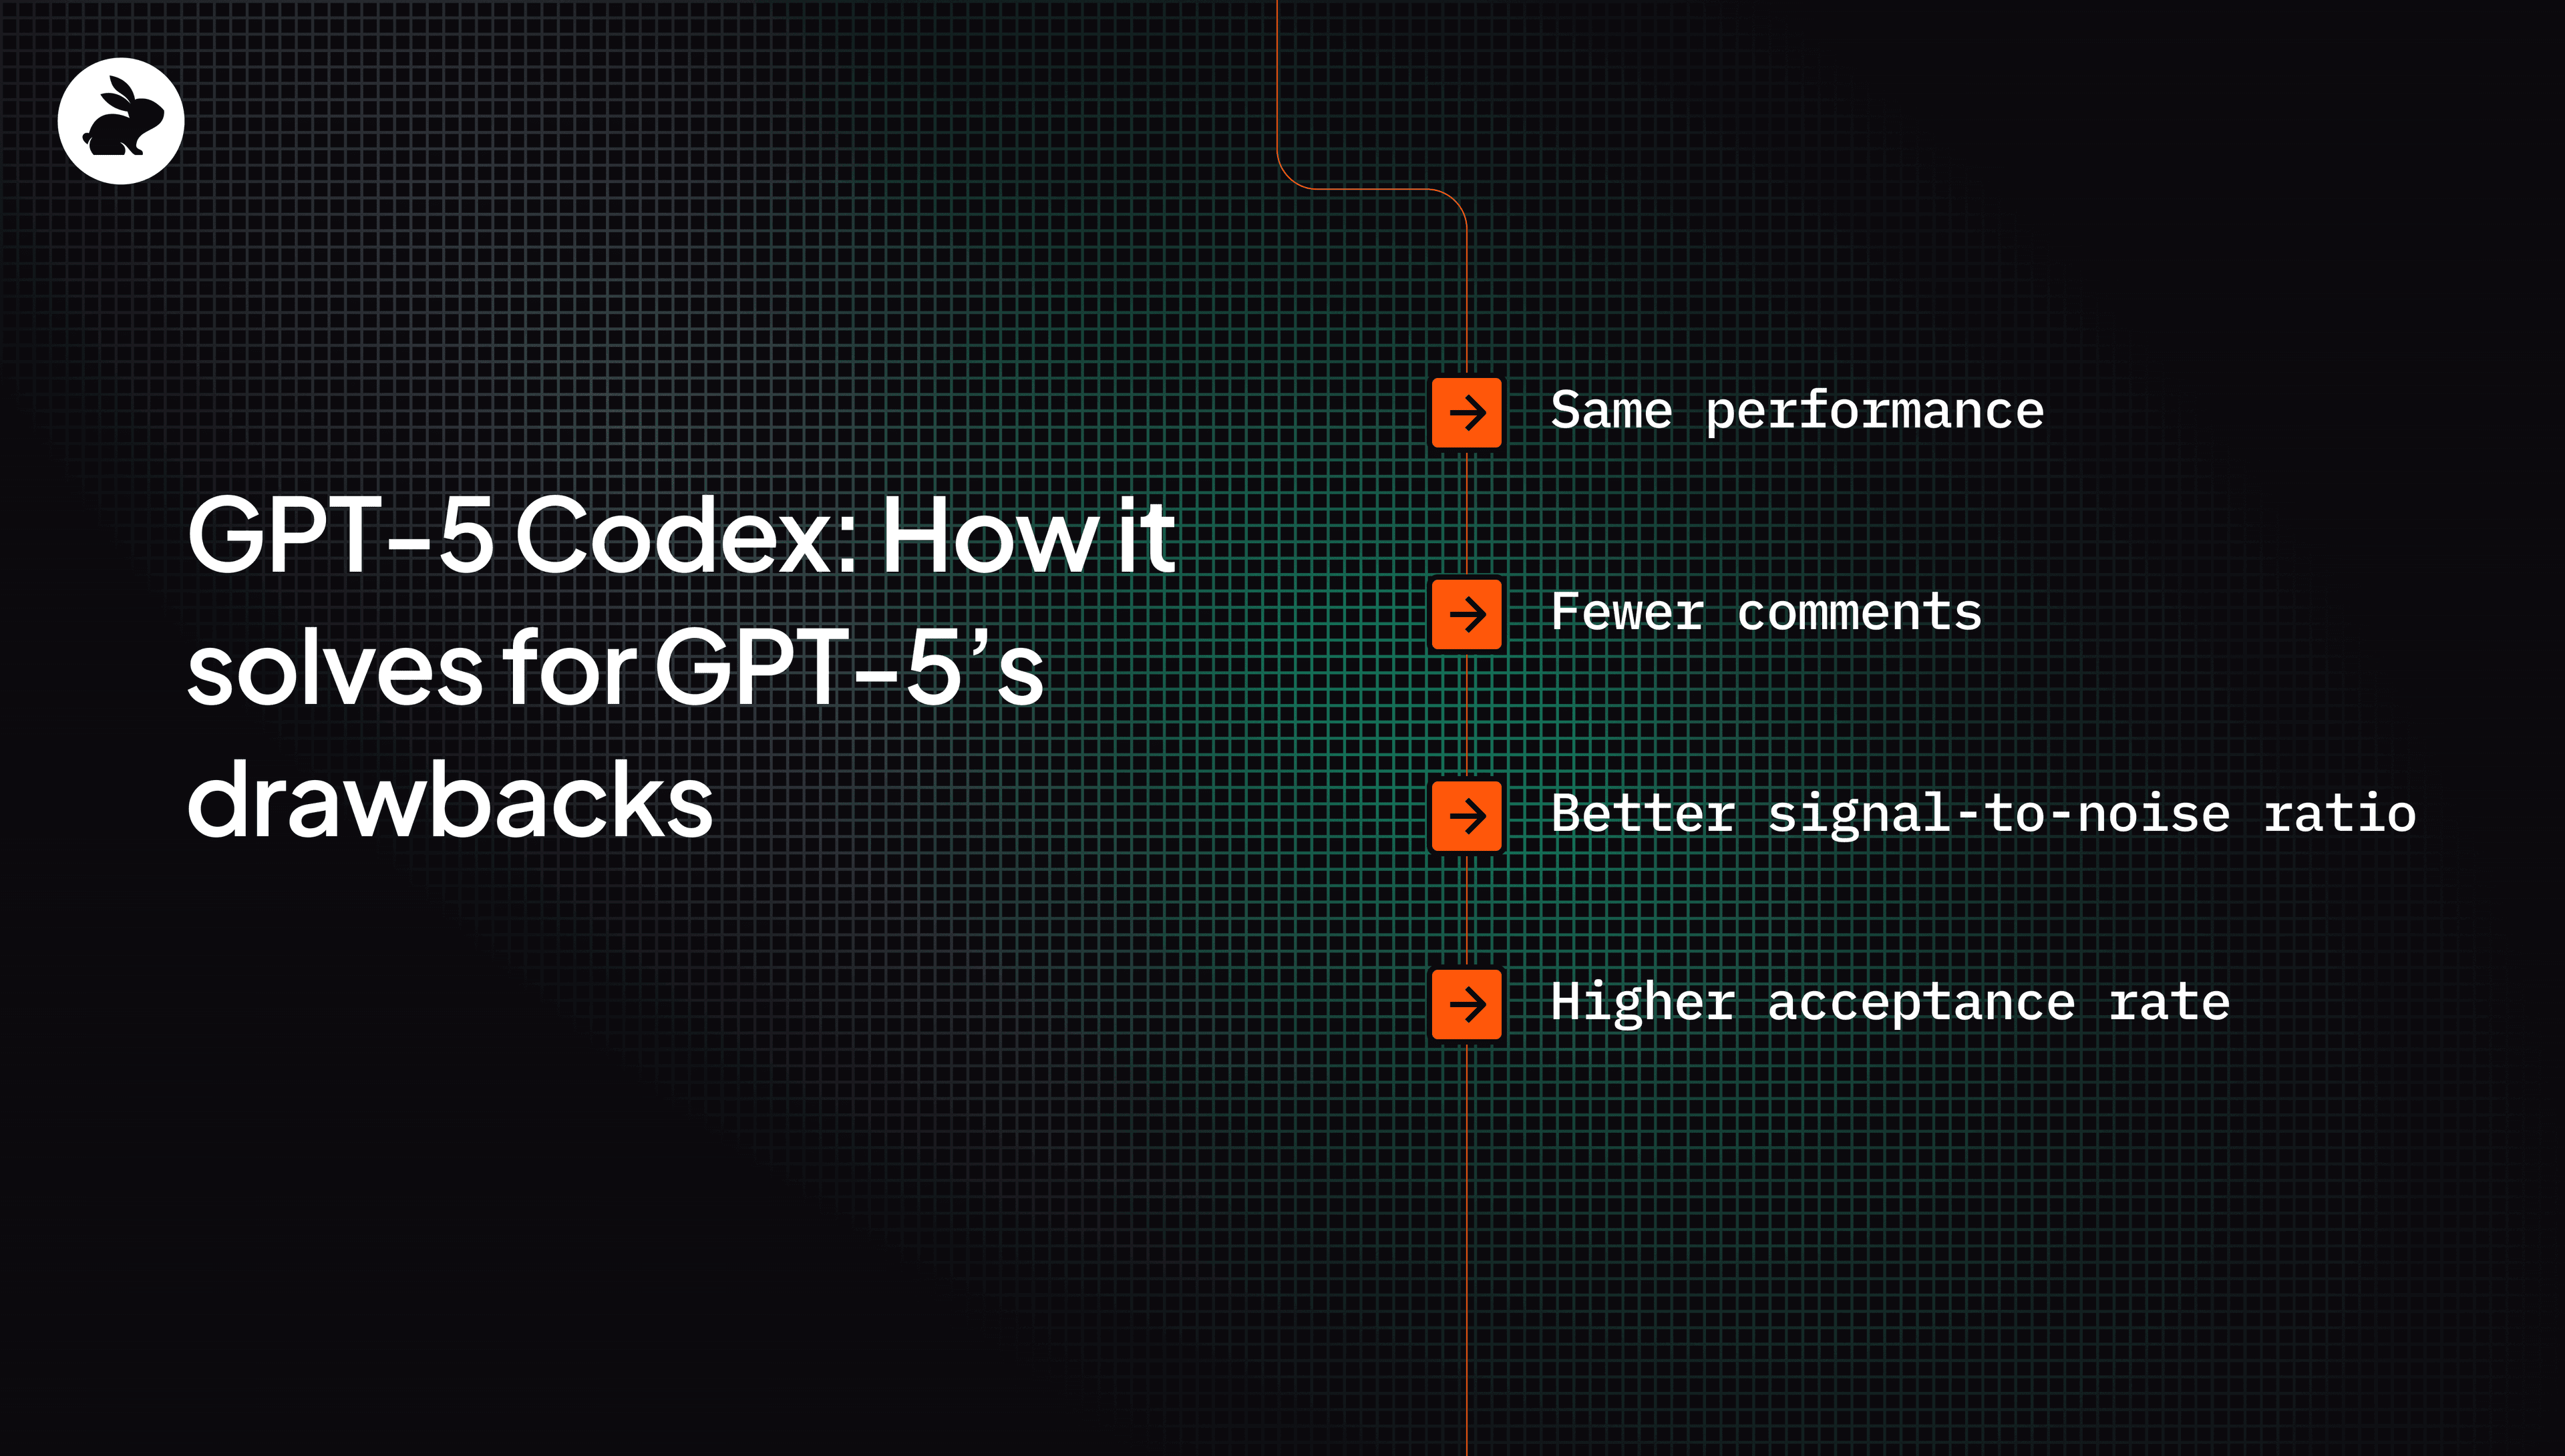
GPT-5 Codex: How it solves for GPT-5's drawbacks
CodeRabbit’s code reviews help developers fix bugs and ship code. We recently wrote about benchmarking GPT-5 and opined that the model was a generational leap in reasoning for our use case of AI code reviews. As we rolled out to our wider user base, ...
We raised $60 million last week… so we made a funny video
Last week, we announced CodeRabbit’s $60 million Series B. To celebrate, we did what any responsible, developer-focused software company would do: we made a funny video. Not with all the money, to be clear. But we did decide to celebrate with somethi...
CodeRabbit commits $1 million to open source
Open source is the foundation of modern software development. From package managers and developer tools to frameworks and infrastructure, open source projects power nearly every piece of software we use today – including CodeRabbit itself. These proj...