
CodeRabbit author
Juan Pablo Flores
12 articles · writing here since April 2026
Latest article
Fable 5.1 review: Coding tests and code review results
Read CodeRabbit’s Fable 5.1 review, including coding tasks, code review results, latency, and the trade-offs to test before switching models.
More articles by Juan Pablo Flores
Introducing the CodeRabbit plugin for Cursor
Install the CodeRabbit plugin for Cursor and run focused code reviews from the same Agent session where you build.
08.25.26
Teaching NVIDIA Nemotron 3.5 Lightning to route code reviews
CodeRabbit worked with NVIDIA and Baseten to post-train NVIDIA Nemotron 3.5 Lightning for one of CodeRabbit's highest-volume routing tasks, improving route agreement while reducing estimated inference cost.
08.11.26
GPT-5.6 Sol and Terra: Coding, code review, and cost
Compare GPT-5.6 Sol and Terra for coding agents and code review. Explore CodeRabbit’s benchmark results, follow-through, review quality, and cost trade-offs.
07.09.26
Claude Sonnet 5 review: Coding, code review, and cost
Compare Claude Sonnet 5 with Sonnet 4.6 and flagship models using hands-on coding work, CodeRabbit review results, and practical cost trade-offs.
06.30.26
Fable 5 review: Coding tasks and code review results
See how Fable 5 performs in coding tasks and CodeRabbit’s review tests, including bug coverage, comment precision, and long-running agent behavior.
06.09.26
Nemotron 3 Ultra: Coding workflows and code review benchmarks
Explore Nemotron 3 Ultra for coding workflows, with CodeRabbit review benchmarks covering quality, latency, retries, and structured-output reliability.
06.04.26
Opus 4.8 benchmark results for AI code review and code generation
Opus 4.8 is the best model we have used for long-horizon agentic coding and code generation, and it holds its own on code review out of the box.
05.28.26
How we built the CodeRabbit plugin for Codex
How CodeRabbit built their Codex plugin — lessons on skill design, auth handling, CLI vs app output, and keeping code review inside the developer flow.
04.28.26
What changed in OpenAI GPT-5.5: better judgment, stronger coding, better signal
GPT-5.5 benchmark results from CodeRabbit show improved code review precision, higher signal, and better performance in real workflows.
04.23.26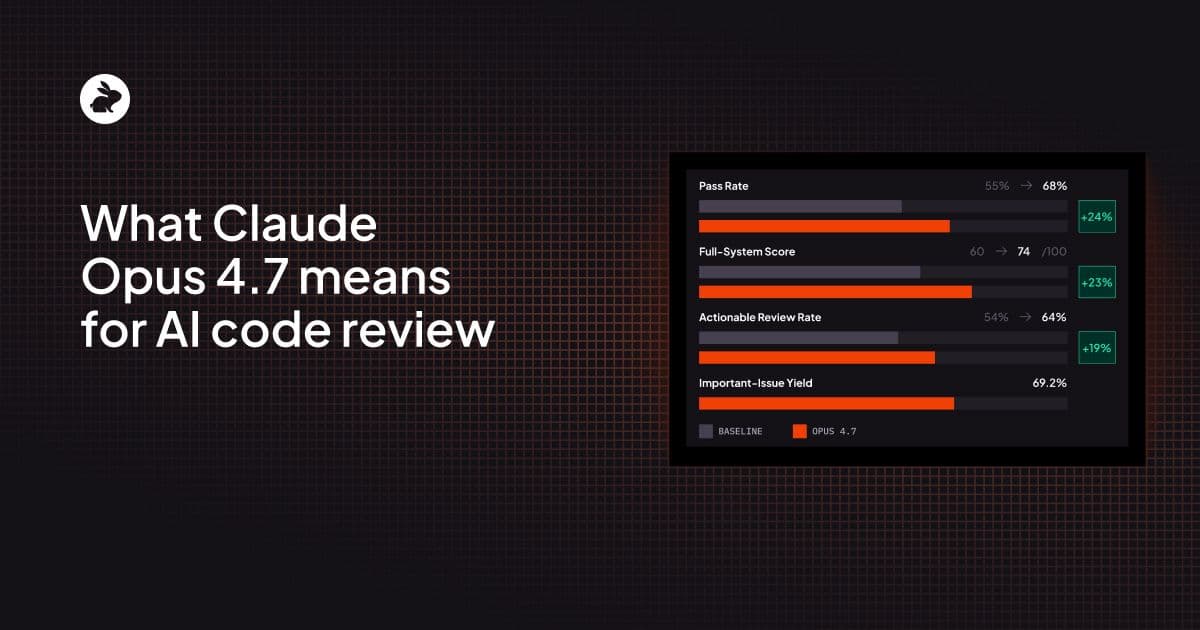
What Claude Opus 4.7 means for AI code review
Claude Opus 4.7 outperformed in 100 evaluations across real open-source pull requests—finding more real bugs, delivering more actionable feedback, and reasoning across files better than anything we’ve tested.
04.16.26
Introducing the CodeRabbit plugin for Codex
Get AI-powered code reviews without leaving Codex. The CodeRabbit plugin runs reviews inside your session, catches bugs before PRs, and requires zero workflow changes to set up.
04.15.26