All articles
Open-source reviews on CodeRabbit topped 1 million in a single month
See which open-source projects ran the most CodeRabbit reviews in September and how we’re backing maintainers through a commitment of more than $10 million to open source.
The feature works. But does it belong?
TRM Labs’ Rahul Raina and CodeRabbit’s Harjot Gill on choosing, validating, and shipping work as agents take on more development.
Introducing collaborative coding: Build together with Slack Code and CodeRabbit Agent for Slack
Bring the people who know each part of a coding task into one shared Slack Code channel, where they can shape the spec and build with CodeRabbit Agent for Slack.
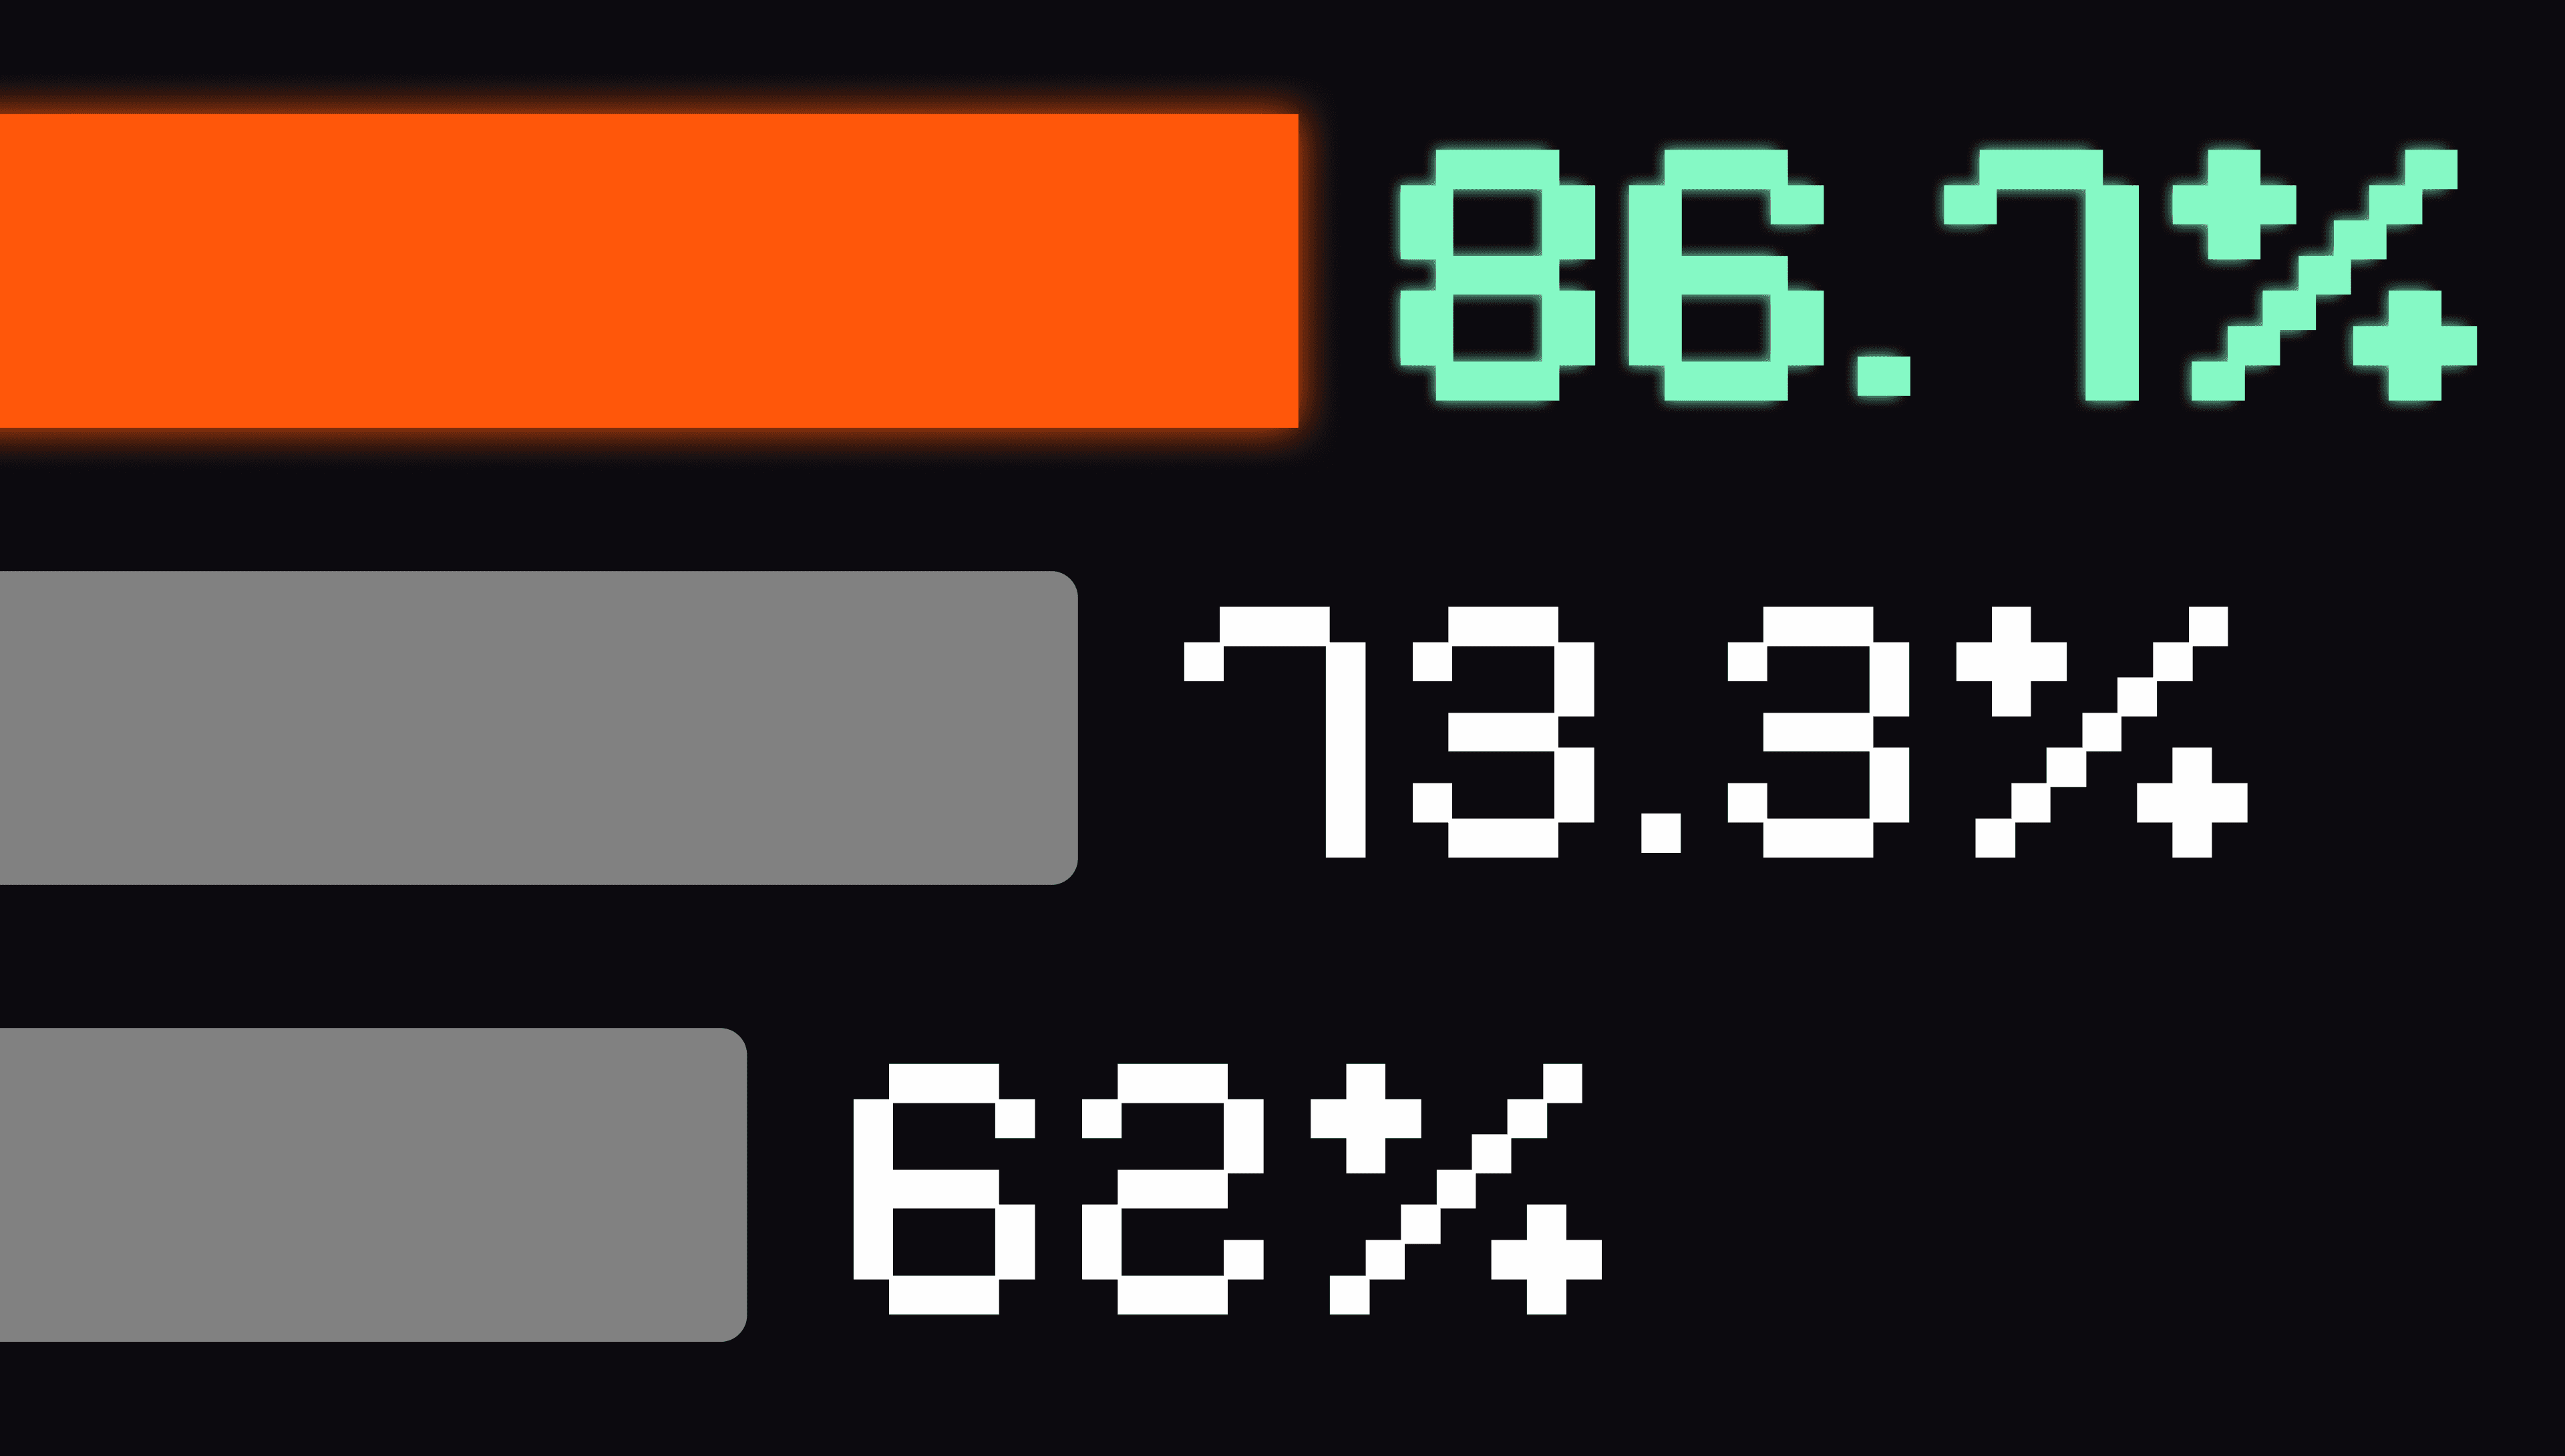
How CodeRabbit Security performed on a real-world vulnerability benchmark
CodeRabbit Security led three other systems in our vulnerability-detection benchmark. Here’s what we tested and how we scored it.
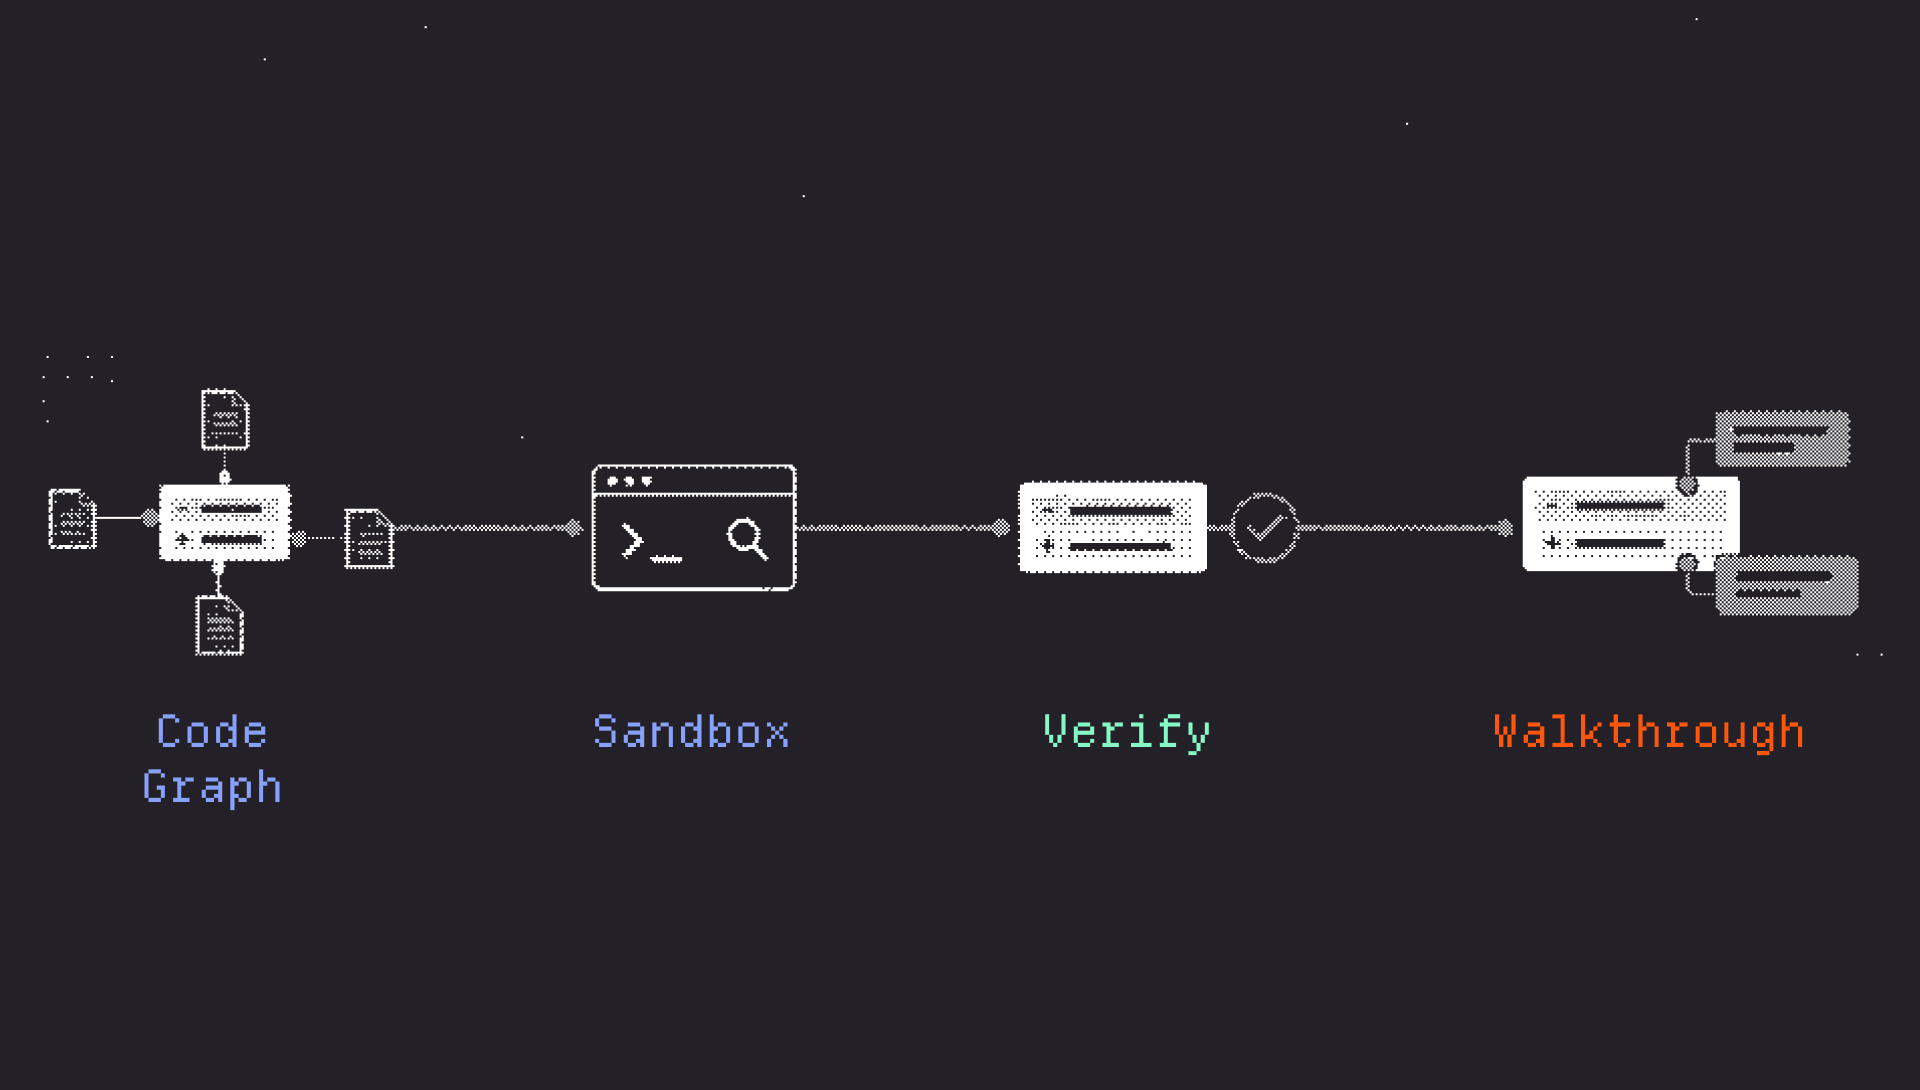
How independent AI code review builds trust in agent-generated changes
Independent AI code review gives teams evidence to trust proposed changes, supported by CodeRabbit’s governance and control layer for agentic software development.
The Merge: What if your ‘if-statements’ could think?
TypeSafe's Allie Laabs explains how to find Jev-shaped problems in your code, why you should ask every question up front, and why coding agents still need help getting it right.
CodeRabbit joins the OpenAI Marketplace
OpenAI customers can apply their existing OpenAI spend commitment towards CodeRabbit through the OpenAI Marketplace, simplifying procurement.
Claude Sonnet 5.5 for code review: More catches than Sonnet 5, in half the time
We benchmarked Claude Sonnet 5.5 for AI code review against Sonnet 5 and Opus 5.5: which bugs it catches, how fast it reviews, and what a review costs.
The Merge: Your tests pass. Can your agent finish the job?
Cua AI co-founder Francesco Bonacci explains why developers need to check whether AI agents finish the job, even when the tools they use work correctly.
Catch the latest, right in your inbox.

GetStarted in2 clicks.